Showing posts with label Amazon VPC. Show all posts

Friday, June 12, 2015

27 Best Practice Tips on Amazon Web Services Security Groups

AWS Security Groups are one of the most used and abused configurations inside an AWS environment if you are using them on cloud quite long. Since AWS security groups are simple to configure, users many times ignore the importance of it and do not follow best practices relating to it. In reality, operating on AWS security groups every day is much more intensive and complex than configuring them once. Actually, nobody talks about it! So in this article, I am going to share our experience in dealing with AWS Security groups since 2008 as a set of best practice pointers relating to configuration and day to day operations perspective.
In the world of security, proactive and reactive speed determines the winner. So a lot of these best practices should be automated in reality. In case your organizations' Dev/Ops/Devops teams needs help with security group best practices automation, feel free to contact me.

AWS released so many features in the last few years relating to Security, that we should not visualize Security groups in isolation, It just does not make sense anymore. The Security Group should always be seen in the overall security context, with this I start the pointers.

Practice 1:  Enable AWS VPC Flow Logs for your VPC or Subnet or ENI level. AWS VPC flow logs can be configured to capture both accept and reject entries flowing through the ENI and Security groups of the EC2, ELB + some more services. This VPC Flow log entries can be scanned to detect attack patterns,alert abnormal activities and information flow inside the VPC and provide valuable insights to the SOC/MS team operations.

Practice 2: Use AWS Identity and Access Management (IAM) to control who in your organization has permission to create and manage security groups and network ACLs (NACL). Isolate the responsibilities and roles for better defense. For example, you can give only your network administrators or security admin the permission to manage the security groups and restrict other roles.

Practice 3: Enable AWS Cloud Trail logs for your account. The AWS Cloud Trail will log all the security group events and it is needed for management and operations of security groups. Event streams can be created from AWS Cloud Trail logs and it can be processed using AWS Lambda. For example : whenever a Security Group is deleted , this event will be captured with details on the AWS Cloud Trail logs. Events can be triggered in AWS Lamdba which can process this SG change and alert the MS/SOC on the dashboard or email as per your workflow. This is a very powerful way of reacting to events within span of <7 minutes. Alternatively, you can process the AWS Cloud Trail logs stored in your S3 every X frequency as a batch and achieve the above. But the Operation teams reaction time can vary depending on generation and polling frequency of the AWS Cloud Trail logs. This activity is a must for your operations team.

Practice 4: Enable AWS App Config for your AWS account. App records all events related to your security group changes and can even send emails.

Practice 5: Have proper naming conventions for the Amazon Web Services security group. The naming convention should follow a enterprise standards. For example it can follow the notation: "AWS Region+ Environment Code+ OS Type+Tier+Application Code"
Security Group Name - EU-P-LWA001
AWS Region ( 2 char ) = EU, VA, CA etc
Environment Code (1 Char)  = P-Production , Q-QA, T-testing, D-Development etc
OS Type (1 Char)= L -Linux, W-Windows etc
Tier (1 Char)= W-Web, A-App, C-Cache, D-DB etc
Application Code ( 4 Chars) = A001
We have been using Amazon Web Services from 2008 and found over the years managing the security groups in multiple environments is itself a huge task. Proper naming conventions from beginning is a simple practice, but will make your AWS journey manageable.

Practice 6: For security in depth, make sure your Amazon Web Services security groups naming convention is not self explanatory also make sure your naming standards stays internal. Example : AWS security group named UbuntuWebCRMProd is self explanatory for hackers that it is a Production CRM web tier running on ubuntu OS. Have an automated program detecting AWS security groups with Regex Pattern scanning of AWS SG assets periodically for information revealing names and alert the SOC/Managed service teams.

Practice 7: Periodically detect, alert or delete AWS Security groups not following the organization naming standards strictly. Also have an automated program doing this as part of your SOC/Managed service operations.  Once you have this stricter control implemented then things will fall in line automatically.

Practice 8: Have automation in place to detect all EC2,ELB and other AWS assets associated with Security groups. This automation will help us to periodically detect Amazon Web Services Security groups lying idle with no associations, alert the MS team and cleanse them. Unwanted security groups accumulated over time will create unwanted confusion.

Practice 9: In your AWS account, when you create a VPC, AWS automatically creates a default security group for the VPC. If you don't specify a different security group when you launch an instance, the instance is automatically associated with the appropriate default security group. It will
allow inbound traffic only from other instances associated with the "default" security group and allow all outbound traffic from the instance. The default security group specifies itself as a source security group in its inbound rules. This is what allows instances associated with the default security group to communicate with other instances associated with the default security group. This is not a good security practice. If you don't want all your instances to use the default security group, you can create your own security groups and specify them when you launch your instances. This is applicable to EC2 , RDS , ElastiCache and some more services in AWS. So detect "default" security groups periodically and alert to the SOC/MS.

Practice 10: Alerts by email and cloud management dash board should be triggered whenever critical security groups or rules are added/modified/deleted in production.  This is important for reactive action of your managed services/security operations team and audit purpose.

Practice 11 : When you associate multiple security groups with an Amazon EC2 instance, the rules from each security group are effectively aggregated to create one set of rules. AWS uses this set of rules to determine whether to allow access or not. If there is more than one SG rule for a specific port, AWS applies the most permissive rule. For example, if you have a rule that allows access to TCP port 22 (SSH) from IP address 203.0.113.10 and another rule that allows access to TCP port 22 for everyone, then everyone will have access to TCP port 22 because permissive takes precedence.
Practice X.1 : Have automated programs detecting EC2 associated with multiple SG/rules and alert the SOC/MS periodically. Condense the same manually to 1-3 rules max as part of your operations.
Practice X.1 : Have automated programs detecting conflicting SG/rules like restrictive+permissive rules together and alert the SOC/MS periodically.

Practice 12 : Do not create least restrictive security groups like 0.0.0.0/0 which is open to every one.
Since web servers can receive HTTP and HTTPS traffic open, only their SG can be permissive like
0.0.0.0/0,TCP, 80, Allow inbound HTTP access from anywhere
0.0.0.0/0,TCP, 443, Allow inbound HTTPS access from anywhere
All least restrictive SG created in your account should be alerted to SOC/MS teams immediately.

Practice 13: Have a security policy not to launch servers with default ports like 3306, 1630, 1433, 11211, 6379 etc. If the policy has to be accepted, then security groups also have to be created on the new hidden listening ports instead of the default ports. This provides a small layer of defense, since one cannot infer the information from the security group port on the EC2 service it is protecting. Automated detection and alerts should be created for SOC/MS, if security groups are created with default ports.

Practice 14: Applications which require stricter compliance requirements like HIPAA, PCI etc to be met need end to end transport encryption to be implemented on server back end in AWS. The communication from ELB to Web->App->DB->Others tiers need to be encrypted using SSL or HTTPS. This means only secured ports like 443, 465, 22 are permitted in corresponding EC2 security groups. Automated detection and alerts should be created for SOC/MS if security groups are created on secure ports for regulated applications.

Practice 15: Detection , alert and actions can be taken by parsing the AWS Cloud Trail logs based on usual patterns observed in your production environment
Example:
15.1 :If a port was opened and closed in <30 or X mins in production can be a candidate for suspicious activity if it is not normal pattern for your production
15.2 :If a permissive Security Group was created and closed in <30 or X mins can be a candidate for suspicious activity if it is not the normal pattern for your production
Detect anomalies on how long a change effected and reverted in security groups in production.

Practice 16: In case ports have to be opened in Amazon Web Services security groups or a permissive AWS security group needs to be applied, Automate this entire process as part of your operations such that a security group is open for X agreed minutes and will be automatically closed aligning with your change management. Reducing manual intervention avoids operational errors and adds security.

Practice 17: Make sure SSH/RDP connection is open in AWS Security Group only for jump box/bastion hosts for your VPC/subnets. Have stricter controls/policies avoid opening SSH/RDP to other instances of production environment. Periodically check , alert and close for this loop hole as part of your operations.

Practice 18: It is a bad practice to have SSH open to the entire Internet for emergency or remote support. By allowing the entire Internet access to your SSH port there is nothing stopping an attacker from exploiting your EC2 instance. The best practice is to allow very specific IP address in your security groups, this restriction improves the protection. This could be your office or on premise or DC through which you connect your jump box.

Practice 19: Too much or Too less: How many security groups for a usual multi tiered web app is preferred is a frequently asked question ?
Option 1 : One security group cutting across multiple tiers is easy to configure, but it is not a recommended for secure production applications.
Option 2: One Security group for every instance is too much protection and tough to manage operationally on longer term
Option 3: Individual Security group for different tiers of the application, For example : Have separate security groups for ELB, Web , App, DB and Cache tiers of your application stack.
Periodically check whether Option 1 type rule is being created in your production and alert the SOC/MS.

Practice 20: Avoid allowing  UDP or ICMP for private instances in Security groups. Not a good practice unless specifically needed.

Practice 21: Open only specific ports, Opening range of ports in a security group is not a good practice. In the security group you can add many inbound ingress rules, While opening the ports it is always advised to open for specific ports like 80,443, etc rather than range of ports like 200-300.


Add rules for communication between associated instances

Practice 22: Private Subnet instances can be accessed only from the VPC CIDR IP range. Opening instances to the public IP ranges is a possibility , but it does not make any sense. E.g., Opening HTTP to 0.0.0.0/0 in the SG of the private subnet instance does not make any sense. So detect and cleanse such rules.

Practice 23: AWS CloudTrail log captures the events related security. AWS lambda events or automated programs should trigger alerts to operations when abnormal activities are detected. For example:
23.1:Alert when X number of SG were added/deleted at "Y" Hours or Day by IAM user / Account
23.2:Alert when X number of SG Rules were added/deleted at "Y" Hours or Day by IAM user / Account

Practice 24: In case you are an enterprise make sure all security groups related activities of your production are part of your change management process. Security Group actions can be manual or automated with your change management in an enterprise.
In case you are an agile Startup or SMB and do not have complicated Change management process, then automate most of the security group related tasks and events as illustrated above on various best practices. This will bring immense efficiency into your operations

Practice 25: Use outbound/egress security groups wherever applicable within your VPC. Restrict FTP connection to any server on the Internet from your VPC. This way you can avoid data dumps and important files getting transferred out from your VPC. Defend harder and make it tougher !

Practice 26: For some tiers of your application, use ELB in front your instance as a security proxy with restrictive security groups - restrictive ports and IP ranges. This doubles your defense but increases the latency.

Practice 27: Some of the tools we use in conjunction to automate and meet above best practices are ServiceNow, Amazon CFT, AWS API'S, Rundeck, Puppet, Chef, Python , .Net and Java automated programs.

Note : In case your organizations Dev/Ops/Devops teams needs help on security group best practices automation on points listed above, feel free to contact me harish11g.aws@gmail.com

Tuesday, April 22, 2014

Loading Big Index Data into newly launched Amazon CloudSearch engine

Search tier is the most critical section of many online verticals like travel, e-commerce, classifieds etc. If users cannot search products efficiently they will not make their buying decisions properly, which in turn massively affects the revenues of these companies. Most of them are usually powered by Apache Solr, FAST , Autonomy, ElastiSearch etc.  AWS also has a Search Service called CloudSearch which is a fully-managed service in the cloud that makes it easy to set up, manage, and scale a search solution for your website. Amazon CloudSearch relieves you from the worry of hardware provisioning, setup, and maintenance. As your volume of data and traffic fluctuates, Amazon CloudSearch automatically scales to meet your needs.

In AWS infrastructure Apache Solr has been the king and the software to beat till now, recently it has got heavy competitor in the form of Amazon CloudSearch - API 2013-01-01. 
API version 2013-01-01 of Amazon CloudSearch is internally powered by customized version of Apache Solr Engine, and it is specifically designed for running highly scalable and available search on Amazon Web Services Cloud. This 2013 CloudSearch API has lots of similarities with Apache Solr and customers can easily migrate to this version and leverage the benefits of Amazon Cloud Infrastructure. We are already hearing many AWS customers are planning their migration from FAST, Solr and A9 Engine into the Amazon CloudSearch - 2013-01-01 API engine. 

My team is already migrating couple of customers into this Amazon CloudSearch 2013-01-01 API and i have shared our experience on this process for the benefit of AWS community.

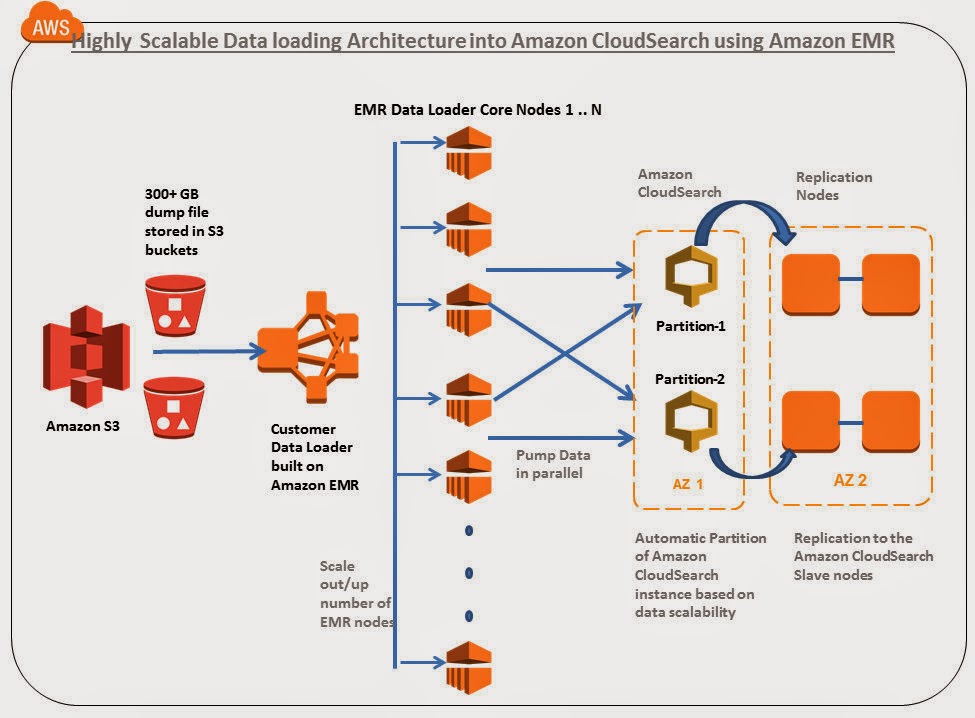
Reference Migration Architecture and requirements:


In this article i am going to explore how to 

  • Migrate a 300+ GB index containing close to 247+ million records distributed in 105 searchable fields in a highly scalable /parallel manner in AWS infrastructure.
  • 300 + GB index file is stored in Amazon S3
  • Custom Data loader program built on Amazon Elastic MapReduce is used for parallel loading
  • Around ~6 Search.M2.2Xlarge are created with 2 partitions and 5 replication count
  • Around 10+ M1.large EMR Core nodes are for Data loading. This loader can be increased to hundreds of nodes depending upon the volume and velocity of data pump required.
  • Amazon CloudSearch Infrastructure provisioning, Automated partitioning, replication count are handled by AWS.   

Lets get into the details below:

Step 1)Create a new Amazon CloudSearch Domain: We have named the search domain as "bigdatasearch" and chose the search instance type as search.m2.2xlarge.  Since we are planning to pump and query a 300 GB index with millions of document, it did not make sense for us to chose a smaller instance type of Amazon CloudSearch.  Usually the base instance type can be selected based on the number and size of the documents you are planning to maintain in the Amazon CloudSearch. 
Note: Here we have chosen replication count as 5.  This is little strange in a distributed architecture because usually more replication count for the master decreases the speed of document upload. But when we were playing with Amazon CloudSearch we observed that it is increasing the speed of uploads. In addition we also observed the following :

  • If we keep the replication count 0 or less, use a smaller search instance type and pump documents in parallel from multiple nodes, either the Amazon CloudSearch Server is failing sometimes or error rates are high.
  • If we keep the replication count 0 or less , use a larger search instance type and pump documents in parallel from multiple nodes, internally Amazon Cloud Search itself is creating 3-5 nodes and it shows in the replication count. Waiting to discuss with AWS SA folks on this behavior.


We will be utilizing distributed uploading technique which we custom built using Amazon Elastic MapReduce to pump data to the Amazon CloudSearch server. This technique enables us to write more Index data in parallel.  

Step 2) Select how you would like to create the Amazon CloudSearch Schema: Here we have chosen Manual setup, since we already have schema to be migrated to Amazon CloudSearch.


Next step is to Add index fields to create your Amazon CloudSearch Schema configuration.

Step 3)Adding Amazon CloudSearch Index Fields: Once all the fields have been configured in the schema, click on continue button. In the schema file used we have 100+ fields to be indexed for this particular search domain.


Step 4) Review the setup configurations and launch:
We have 100+ Index fields with scaling options instance type as m2.2xlarge and replication count 5 in the "bigdatasearch" domain.


Step 5 ) Wait till the Amazon CloudSearch Infrastructure is provisioned for you on the back. Usually it takes 10 minutes, it will also list if there is any error encountered when creating the index fields.


Once the Amazon CloudSearch infrastructure is provisioned at the back end , you should notice the "bigdatasearch" domain is "Active". The search and Document endpoints are published and currently no of searchable document is "0". There is only 1 CloudSearch Index Partition (Shards) and 5 search.m2.2xlarge instances.


Step 6)Configuring Synonyms: We have 2+ MB of Synonyms which needs to be configured into the Amazon CloudSearch domain. For this, we used Cloud Search cli-toolkit to upload synonyms to Cloud Search.

cs-configure-analysis-scheme -d bigdatasearch --name customanalysisscheme --lang en -e cloudsearch.ap-southeast-1.amazonaws.com --synonyms customsynonyms.txt


Since the volume of index data is huge (300+ GB) we have created a Custom Data Loader built on Amazon Elastic MapReduce to pump the data in parallel into Amazon CloudSearch. Since it is built on Amazon Elastic MapReduce,  we can use the same program without modification for scale to upload TB's of index into the search system with hundreds of Data loader EMR core/task nodes. 

Step 7) Create Amazon Elastic MapReduce Data Loader Cluster Configuration:


Step 8) Configure the Elastic MapReduce (EMR) Capacity: We are using 10 M1.Large core node instances for uploading the data from inside AWS VPC. Depending upon the Data size (GB->TB) and Upload hours we can increase the EMR core nodes capacity and number to speed up the data pump (upload) process.


To know more about How Spot instances can save cost on Amazon EMR ? refer URL AWS Cost Saving Tip 12: Add Spot Instances with Amazon EMR

Step 9)Add Custom data loader program Jar to EMR: 
We have exported the data from a MSSQL server as flat UTF-8 dump file and stored it in Amazon S3. We are giving the 300+ GB Dump file as the input for the Amazon EMR CloudSearch Data Loader program to upload into Amazon CS in parallel. Buckets configurations of the Data Loader jar, Input, output and log files are configured in this screen


Step 10) Configure Amazon CloudSearch Access Policies:  We need to open Cloud Search security group access policies to accept upload requests from EMR cluster inside VPC. Configure static IP’s of all the instances or IP range of the data loader clients


Step 11)Run the Amazon Elastic MapReduce Data loader job :


Step 12) Analyzing the Amazon EMR Data loader Job Output:
Output of the JOB can be seen in the AWS EMR JOB logs. Here are few details:

  • “Map output records” in the log tells how many records are inserted into the Amazon CloudSearch , we can observe close to 247,681,520 documents(247+ million) are pumped.
  • “Bytes Read” in the output tells what is size of data set which the JOB has read. We can observe 322387978332 bytes which is equivalent to 300+ GB of index in the Amazon CloudSearch
  • The entire pumping process took ~30 hours with 10 m1.large core nodes for us. We observed that increasing the number of Data loader EMR nodes or their capacity improves the upload speed drastically.


Step 13) Clean up : Reset Replication Count to level of HA needed ideally 1-2 nodes. Once the Job is completed, Revert back the Security Access Policies in Amazon cloud search. Terminate the EMR Cluster and clean any leftover resources.

Step 14) Analyzing the CloudSearch Dashboard :
We observed that it takes some time for cloud search to reflect actual count of the indexed documents.
After the pumping of 300 + GB index you can observe that currently 2 Amazon CloudSearch partitions ( shards) are used to distribute 247+ million documents with 100+ index fields. This is tremendous cost savings compared to A9 powered Amazon CloudSearch. Amazon CloudSearch has automatically created shards based on the volume of data pumped in to the system. This is cool !!!, it reduces the maintenance headache of the infra admins. If the Amazon CloudSearch team can make this partition concept as configurable parameter in future it will be useful. 


Step 15) Executing a Sample Search queries: We are executing a some sample product search queries on the "bigdatasearch" domain to check whether everything is fine. Distributed query was fired and Results came Sub Second from one of the partitions.


In short, It is cost effective compared to old A9 powered CloudSearch, Automated scaling of replication counts for request scalability, automated scaling of partitions for data scalability relieves the infra admin headaches, strong apache Solr pedigree and its long list of feature additions in coming months will make it more interesting.  

After working with this service few weeks, we feel it is going to become the major search service on AWS in coming years, giving tough fight for Apache Solr and ElastiSearch deployments on EC2. 

This article was co authored with Ankit @8Kmiles.

Thursday, February 6, 2014

ElastiCache Redis : How to Backup & Launch from RDB Snapshots ?


ElastiCache Redis is a powerful KV store offering both in-memory and persistent store for Key Values.When we persist data in ElastiCache Redis, it is obvious that we need to constantly backup Redis to recover the data during failures. By default there is no option to easily create the snapshot from the running ElastiCache Redis cluster. We need to install Redis on Self Managed EC2 node and point it to ElastiCache Redis Master for the snapshot process. This post explains about the step by step method for Redis cluster snapshot creation.

Redis Snapshot Architecture :

  • ElastiCache cluster with master redis node of size cache.m1.large in AZ1 and Replication group with one read replica node of size cache.m1.large in AZ2
  • Self managed Redis installed on EC2 for snapshots on AZ1


Stage 1: Creating a Snapshot for ElastiCache redis Persistent store.

Step 1) Launch an EC2 instance on the same Availability zone where the ElastiCache Redis master node runs. 
If the Redis Snapshot EC2 node is temporary (or) replication/Backup performance is very critical then keep the Redis Snapshot node in the same AZ as the ElastiCache Redis Master Node.  
If Redis Snapshot node is going to permanently run and high availability of the backup mechanism is very critical, run this on different AZ from master redis node. 

Step 2)Download and install the Redis software on your newly launched EC2 instance. Make sure the Redis snapshot ec2 version and ElastiCache Redis Master version are compatible.
$ wget http://redis.googlecode.com/files/redis-2.6.4.tar.gz
$ tar xzf redis-2.6.4.tar.gz
$ cd redis-2.6.4
$ make


Step 3)Start the Redis Server on the newly launched EC2 instance. It will be listening on the port 6379
# src/redis-server 
[1513] 10 Jan 10:25:45.083 * Max number of open files set to 10032 
[1513] 10 Jan 10:25:45.085 # Server started, Redis version 2.6.4 


Step 4)Open another terminal window and connect locally to the Redis Snapshot EC2 instance 
# src/redis-cli -h localhost -p 6379 
redis localhost:6379> 


Step 5)To synchronize the data between the local Redis Snapshot EC2 instance and the ElastiCache Redis master use the following command in the Redis Snapshot EC2. 
SLAVEOF redissnapshot.qcdze2.0001.usw2.cache.amazonaws.com 6379

where "redissnapshot.qcdze2.0001.usw2.cache.amazonaws.com 6379" is the endpoint of the ElastiCache Master Redis node.
Bringing a Additional Redis EC2 node for snapshots into the infrastructure is not ideal. It adds extra cost and manual labor effort to setup, automate and manage this Redis Snapshot EC2. I hope AWS ElastiCache team will release a mechanism where we can easily take the snapshots from the ElastiCache Cluster itself. 
Note: Before this step ensure that security group permissions are opened between the Redis Snapshot EC2 and ElastiCache Redis Cluster.


Step 6)Once the synchronization is done between Redis Snapshot node and ElastiCache Redis Master, you can take snapshot using the command BGSAVE or SAVE in the snapshot EC2 Node. The snapshot file named "dump.rdb" is created in the disk.

Step 7) You can optionally detach it from the ElastiCache cluster by using the command on redis-cli  “SLAVEOF NO ONE”. This step is recommended if your redis cluster size is few GB's and you are backing up persistent data once/4 times a day, as you can save costs by not unnecessarily running your Redis snapshot EC2 instance for 24 hours and automatically bring it up whenever needed.

We conducted a small test to check whether all the above steps are successfully reflected. 

We pumped the ElastiCache Redis cluster with 1.8GB of Data spanning few hundred millions of KV data with each record in few <KB size. We observed the time taken to sync the data is about ~5 minutes on m1.large capacity in same AZ deployment. 

  • If your Redis is heavily used it is better to use Higher EC2 capacities for the ElastiCache Cluster and Snapshot node. Bigger the nodes, better the NW/IO and lesser the replication lag. 
  • If you are running a small cluster with few GB's then creating the Redis Snapshot Node on demand will save costs. If your cluster is big, data is critical and backup frequencies are less, then run Snapshot EC2 node continuously for better performance.


The replication action with timing is detailed below:
[1595] 10 Jan 11:03:06.676 # Server started, Redis version 2.6.4 
[1595] 10 Jan 11:03:06.676 * The server is now ready to accept connections on port 6379 
[1595] 10 Jan 11:03:18.018 * SLAVE OF redissnapshot.qcdze2.0001.usw2.cache.amazonaws.com:6379 enabled (user request) 
[1595] 10 Jan 11:03:18.779 * Connecting to MASTER... 
[1595] 10 Jan 11:03:18.975 * MASTER <-> SLAVE sync started 
[1595] 10 Jan 11:03:18.975 * Non blocking connect for SYNC fired the event. 
[1595] 10 Jan 11:03:18.977 * Master replied to PING, replication can continue... 
[1595] 10 Jan 11:06:03.949 * MASTER <-> SLAVE sync: receiving 1943998490 bytes from master 
[1595] 10 Jan 11:08:13.348 * MASTER <-> SLAVE sync: Loading DB in memory 
[1595] 10 Jan 11:09:37.430 * MASTER <-> SLAVE sync: Finished with success 
[1595] 10 Jan 11:09:37.441 * 100 changes in 300 seconds. Saving... 
[1595] 10 Jan 11:09:39.970 * Background saving started by pid 1635 
[1595] 10 Jan 11:16:44.860 # User requested shutdown... 
[1595] 10 Jan 11:16:44.860 * Saving the final RDB snapshot before exiting. 
[1595] 10 Jan 11:19:10.270 * DB saved on disk 
[1595] 10 Jan 11:19:10.270 # Redis is now ready to exit, bye bye... 

Test whether the same key values are synced between Master Redis Node in ElastiCache Cluster and Redis Snapshot EC2. The below steps illustrate the same: 
# src/redis-cli -h redissnapshot.qcdze2.0001.usw2.cache.amazonaws.com -p 6379 

redis redissnapshot.qcdze2.0001.usw2.cache.amazonaws.com:6379> get 100sent 
"1001234567890123456789012345678901234567890abcdefghijklmopqrstuvwxyz"

redis redissnapshot.qcdze2.0001.usw2.cache.amazonaws.com:6379> get 10sent 
"101234567890123456789012345678901234567890abcdefghijklmopqrstuvwxyz"


Important Observation:
Always sync the Redis Snapshot EC2 node with the ElastiCache Redis master node and not with the read slave in the redis replication group. Following error will be displayed when trying to sync with the slave. 
#Connecting to MASTER...
#MASTER <-> SLAVE sync started
#Non blocking connect for SYNC fired the event.
#Master replied to PING, replication can continue...
# MASTER aborted replication with an error: ERR Can't SYNC with a slave


We tried the above approach to check whether we can reduce the workload on Redis Master node and take the backups from Slave redis Nodes. As AWS as rightly named it is " Redis Read Replica Nodes" and you cannot use it for snapshot replication. 

Stage 2: Launching ElastiCache Redis Cluster from the existing Snapshot taken above.

Step 1) Import the data to the S3 bucket (redisaws) and assign open/download permission for the email id aws-scs-s3-readonly@amazon.com. Note : The aws-scs-s3-readonly account is used exclusively for customers uploading Redis snapshot data from Amazon S3.

Step 2) Launch a new ElastiCache Redis cluster from the "dump.rdb" snapshot taken in the earlier stage 1 - step 6 from Redis Snapshot node. Lets understand what is RDB in detail.

  • RDB is a very compact single file point in time representation of your Redis data and are perfect for backups. Being a single compact file it can be transferred to alternate AZ and AWS regions quite fast and is ideal during outages/DR. RDB also allows faster restarts of Redis Master with big datasets in new ElastiCache Clusters nodes. Both these points helps us achieve better RPO and RTO during DR scenario using RDB. 
  • RDB needs to fork() often in order to persist on disk using a child process. Fork() can be time consuming if the dataset is big, and may result in Redis Master to stop serving clients for some millisecond or even for one second if the dataset is very big and the CPU performance is not great. Also since the Redis Snapshot instance in this architecture is not used for accepting reads/writes and it is primarily used only for replication + snapshot it will add again minimal load on the master node during replication. Factor the ElastiCache Master Redis node capacity taking both these parameters into consideration.
  • Note : RDB is NOT good if you need to minimize the chance of data loss in case Redis Master stops working. It is suggested to use RDB model with ElastiCache Redis Replication group cluster for better Availability and integrity.


Step 3) Once the ElastiCache cluster is launched. Connect to the cluster endpoint and check for the existence of the same key values tested in the dump.


src/redis-cli -h rds.qcdze2.0001.usw2.cache.amazonaws.com -p 6379 

redis rds.qcdze2.0001.usw2.cache.amazonaws.com:6379> get 10sent 
"101234567890123456789012345678901234567890abcdefghijklmopqrstuvwxyz" 

redis rds.qcdze2.0001.usw2.cache.amazonaws.com:6379> get 100sent 
"1001234567890123456789012345678901234567890abcdefghijklmopqrstuvwxyz" 
You can notice from the above that the key values are same and the new ElastiCache node was created properly with original data.


This post was co authored with Senthil 8K Miles


Friday, January 31, 2014

25 Best Practice Tips for architecting your Amazon VPC

According to me Amazon VPC is one of the most important feature introduced by AWS. We have been using AWS from 2008 and Amazon VPC from the day it was introduced and i strongly feel the customer adoption towards AWS cloud gained real momentum only after the introduction of VPC into the market. 
Amazon VPC comes with lots of advantages over the limitations faced in Amazon Classic cloud like: Static private IP address , Elastic Network Interfaces :  possible to bind multiple Elastic Network Interfaces to a single instance, Internal Elastic Load Balancers, Advanced Network Access Control ,Setup a secure bastion host , DHCP options , Predictable internal IP ranges , Moving NICs and internal IPs between instances, VPN connectivity, Heightened security etc. Each and everything is a interesting topic on its own and i will be discussing them in detail in future. 

Today i am sharing some of our implementation experience on working with hundreds of Amazon VPC deployments as best practice tips for the AWS user community. You can apply some of the relevant ones in your existing VPC or use these points as part of your migration approach to Amazon VPC.

Please also look into 27 Best practices on AWS Security Groups to understand the relation with Amazon VPC. 
http://harish11g.blogspot.com/2015/06/best-practices-tips-on-amazon-web-services-security-groups-aws-security-managed-services.html

Practice 1) Get your Amazon VPC combination right: Select the right Amazon VPC architecture first.  You need to decide the right Amazon VPC & VPN setup combination based on your current and future requirements. It is tough to modify/re-design the Amazon VPC at later stage, so it is better to design it taking into consideration your NW and expansion needs for next ~2 years. Currently different types of Amazon VPC setups are available; Like Public facing VPC, Public and Private setup VPC, Amazon VPC with Public and Private Subnets and Hardware VPN Access, Amazon VPC with Private Subnets and Hardware VPN Access, Software based VPN access etc. Choose the one which you feel you will be in next 1-2 years.

Practice 2) Choose your CIDR Blocks: While designing your Amazon VPC, the CIDR block should be chosen in consideration with the number of IP addresses needed and whether we are going to establish connectivity with our data center. The allowed block size is between a /28 netmask and /16 netmask. Amazon VPC can have contain from 16 to 65536 IP addresses. Currently Amazon VPC once created can't be modified, so it is best to choose the CIDR block which has more IP addresses usually. Also when you design the Amazon VPC architecture to communicate with the on premise/data center ensure your CIDR range used in Amazon VPC does not overlaps or conflicts with the CIDR blocks in your On premise/Data center. Note: If you are using same CIDR blocks while configuring the customer gateway it may conflict.
E.g., Your VPC CIDR block is 10.0.0.0/16 and if you have 10.0.25.0/24 subnet in a data center the communication from instances in VPC to data center will not happen since the subnet is the part of the VPC CIDR. In order to avoid these consequences it is good to have the IP ranges in different class. Example., Amazon VPC is in 10.0.0.0/16 and data center is in 172.16.0.0/24 series.

Practice 3) Isolate according to your Use case: Create separate Amazon VPC for Development , Staging and Production environment (or) Create one Amazon VPC with Separate Subnets/Security/isolated NW groups for Production , Staging and development. We have observed 60% of the customer preferring the second choice. You chose the right one according to your use case. 

Practice 4) Securing Amazon VPC : If you are running a machine critical workload demanding complex security needs you can secure the Amazon VPC like your on-premise data center or more sometimes. Some of the tips to secure your VPC are: 

  • Secure your Amazon VPC using Firewall virtual appliance, Web application firewall available from Amazon Web Services Marketplace. You can use check point, Sophos etc for this
  • You can configure Intrusion Prevention or Intrusion Detection virtual appliances and secure the protocols and take preventive/corrective actions in your VPC
  • Configure VM encryption tools which encrypts your root and additional EBS volumes. The Key can be stored inside AWS (or) in your Data center outside Amazon Web Services depending on your compliance needs. http://harish11g.blogspot.in/2013/04/understanding-Amazon-Elastic-Block-Store-Securing-EBS-TrendMicro-SecureCloud.html
  • Configure Privileged Identity access management solutions on your Amazon VPC to monitor and audit the access of Administrators of your VPC.
  • Enable the cloud trail to audit in the VPC environments  ACL policy's. Enable cloud trail : http://harish11g.blogspot.in/2014/01/Integrating-AWS-CloudTrail-with-Splunk-for-managed-services-monitoring-audit-compliance.html
  • Apply anti virus for cleansing specific EC2 instances inside VPC. Trend micro has very good product for this.
  • Configure Site to Site VPN for securely transferring information between Amazon VPC in different regions or between Amazon VPC to your On premise Data center
  • Follow the Security Groups and NW ACL's best practices listed below

Practice 5) Understand Amazon VPC Limits: Always design the VPC subnets in consideration with the expansion in the future. Also understand the Amazon VPC's limits before using the same. AWS has various limitations on the VPC components like Rules per security group, No of route tables and Subnets etc. Some of them may be increased after providing the request to the Amazon support team while few components cannot be increased. Ensure the limitations are not affecting your overall design. Refer URL:
http://docs.aws.amazon.com/AmazonVPC/latest/UserGuide/VPC_Appendix_Limits.html

Practice 6) IAM your Amazon VPC: When you are going to assign people to maintain your Amazon VPC you can create Amazon IAM account with the fine grained permissions (or) use Sophisticated Privileged identity Management solutions available on AWS marketplace to IAM your VPC.

Practice 7) Disaster Recovery or Geo Distributed Amazon VPC Setup : When you are designing a Disaster Recovery Setup plan using VPC or expanding to another Amazon VPC region you can follow these simple rules. Create your Production site VPC CIDR : 10.0.0.0/16 and your DR region VPC CIDR:  172.16.0.0/16. Make sure they do not conflict with on premises subnet CIDR block in event both needs to be integrated to on premise DC as well. After CIDR blocks creation , setup a VPC tunnel between regions and to your on premise DC. This will help to replicate your data using private IP’s. 


Practice 8) Use security groups and Network ACLs wisely:  It is advisable to use security groups over Network ACLs inside Amazon VPC wherever applicable for better control. Security groups are applicable on EC2 instance level while network ACL is applicable on Subnet level.  Security groups are used for White list mostly. To blacklist IPs, one can use Network ACLs.

Practice 9) Tier your Security Groups : Create different security groups for different tiers of your infrastructure architecture inside your VPC. If you have Web, App, DB tiers create different security group for each of them. Creating tier wise security groups will increase the infrastructure security inside Amazon VPC.  EC2 instances in each tier can talk only on application specified ports and not at all ports. If you create Amazon VPC security groups for each and every tier/service separately it will be easier to open a port to a particular service. Don't use same security group for multiple tiers of instances, this is a bad practice. 
Example: Open ports for security group instead of IP ranges : For example : People have tendency to open for port 8080 to 10.10.0.0/24 (web layer) range. Instead of that, open port 8080 to web-security-group. This will make sure only web security group instances will be able to contact on port 8080. If someone launches NAT instance with NAT-Security-Group in 10.10.0.0/24, he won't be able to contact on port 8080 as it allows access from only web security group. 

Practice 10 ) Standardize your Security Group Naming conventions : Following a security group naming conventions inside Amazon VPC will improve operations/management for large scale deployments inside VPC. It also avoids manual errors, leaks and saves cost and time overall.
For example: Simple ones like Prod_DMZ_Web_SG or Dev_MGMT_Utility_SG (or) complex coded ones for large scale deployments like
USVA5LXWEBP001- US East Virginia AZ 5 Linux Web Server Production 001
This helps in better management of security groups. 

Practice 11) ELB on Amazon VPC:  When using Amazon ELB for Web Applications, put all other EC2 instances( Tiers like App,cache,DB,BG etc)  in private subnets as much possible. Unless there is a specific requirement where instances need outside world access and EIP attached, put all instances in private subnet only. Only ELBs should be provisioned in Public Subnet as secure practice in Amazon VPC environment.

Practice 12) Control your outgoing traffic in Amazon VPC: If you are looking for better security, for the traffic going to internet gateway use Software's like Squid or Sophos to restrict the ports,URL,Domains etc so that all traffic go through the proxy tier controlled and it also gets logged. Using these proxy/security systems we can also restrict the unwanted ports, by doing so,  if there is any security compromise to the application running inside Amazon VPC they can be detected by auditing the restricted connections captured from the logs. This helps in corrective security measure. 

Practice 13) Plan your NAT Instance Type: Whenever your Application EC2 instances residing inside private subnet of Amazon VPC are making Web Service/HTTP/S3/SQS calls they go through NAT instance. If you have designed Auto scaling for your application tier and there are chances ten's of app EC2 instances are going to make lots of web calls concurrently, NAT instance will become a performance bottleneck at this juncture. Size your NAT instance capacity depending upon application needs for avoiding performance bottlenecks. Using the NAT instances provides us with advantages of saving cost of Elastic IP and provides extra security by not exposing the instances to outside world for accessing the internet. 

Practice 14) Spread your NAT instance with Multiple Subnets: What if you have hundreds of EC2 instances inside your Amazon VPC and they are making lots of heavy web service/HTTP calls concurrently. A single NAT instance with even largest EC2 size cannot handle that bandwidth sometimes and may become performance bottleneck. In Such scenarios, span your EC2 across multiple subnets and create NAT's for each subnet. This way you can spread your out going bandwidth and improve the performance in your VPC based deployments.

Practice 15) Use EIP when needed: At times you may need to keep a part of your application services to be kept in Public subnet for external communication. It is recommended practice to associate them with Amazon Elastic IP and white list these IP address in the target services used by them 

Practice 16) NAT instance practices : If needed, enable Multi factor authentication on NAT instance. SSH and RDP ports are open only on sources and destination IP's, not global network (0.0.0.0/0). SSH / RDP ports are opened only on static exit IP's not dynamic exit IP's.  

Practice 17) Plan your Tunnel between On-Premise DC to Amazon VPC: 
Select the right mechanism to connect your on premises DC to Amazon VPC. This will help you to connect the EC2 instance via private IP's in a secure manner. 
  • Option 1: Secure IPSec tunnel to connect a corporate network with Amazon VPC (http://aws.amazon.com/articles/8800869755706543) 
  • Option 2 : Secure communication between sites using the AWS VPN CloudHub (http://docs.aws.amazon.com/AmazonVPC/latest/UserGuide/VPN_CloudHub.html)
  • Option 3: Use Direct connect between Amazon VPC and on premise when you have lots of data to be transferred with reduced latency (or) you have spread your mission critical workloads across cloud and on premise. Example: Oracle RAC in your DC and Web/App tier in your Amazon VPC. Contact us if you need help on setting up direct connect between Amazon VPC and DC.

Practice 18) Always span your Amazon VPC across multiple subnets in Multiple Availability zones inside a Region. This helps is architecting high availability inside your Amazon VPC properly. Example: Classification of the VPC subnet : WEB Tier Subnet : 10.0.10.0/24 in Az1 and 10.0.11.0/24 in Az2, Application Tier Subnet :  10.0.12.0/24 and 10.0.13.0/24, DB Tier Subnet :  10.0.14.0/24 and 10.0.15.0/24, Cache Tier Subnet : 10.0.16.0/24 and 10.0.17.0/24 etc

Practice 19) Good security practice is that to have only public subnet with route table which carries route to internet gateway. Apply this wherever applicable.

Practice 20) Keep your Data closer : For small scale deployments in AWS where cost is critical than high availability, It is better to keep the Web/App in same availability zone as of ElastiCache , RDS etc inside your Amazon VPC. Design your subnets accordingly to suit this. This is not a recommended architecture for applications demanding High Availability.

Practice 21) Allow and Deny Network ACL : Create Internet outbound allow and deny network ACL in your VPC. 
First network ACL: Allow all the HTTP and HTTPS outbound traffic on public internet facing subnet. 
Second network ACL: Deny all the HTTP/HTTPS traffic. Allow all the traffic to Squid proxy server or any virtual appliance. 

Practice 22 ) Restricting Network ACL : Block all the inbound and outbound ports. Only allow application request ports. These are stateless traffic filters that apply to all traffic inbound or outbound from a Subnet within VPC. AWS recommended Outbound rules : http://docs.aws.amazon.com/AmazonVPC/latest/UserGuide/VPC_Appendix_NACLs.html

Practice 23) Create route tables only when needed and use the Associations option to map subnets to the route table in your Amazon VPC

Practice 24) Use Amazon VPC Peering (new) : Amazon Web Services has introduced VPC peering feature which is quite useful one. AWS VPC peering connection is a networking connection between two Amazon VPCs that enables you to route traffic between them using private IP addresses. Currently it can be in same AWS region, Instances in either VPC can communicate with each other as if they are within the same network. Since AWS uses the existing infrastructure of a VPC to create a VPC peering connection; it is neither a gateway nor a VPN connection, and does not rely on a separate piece of physical hardware (which essentially means there is no single point of failure for communication or a bandwidth bottleneck).
We have seen it is useful in following scenarios :
  1. Large Enterprises usually run Multiple Amazon VPC in single region and some of their applications are so interconnected that they may need to access them privately + securely inside AWS. Example Active Directory, Exchange, Common business services will be usually interconnected.
  2. Large Enterprise have different AWS accounts for different business units/teams/departments , at times systems deployed by some business units in different AWS accounts need to be shared or need to consume a shared resource privately. Example: CRM , HRMS ,File Sharing etc can be internal and shared. In such scenarios VPC peering comes very useful.
  3. Customer can peer their VPC with their core suppliers to have tighter integrated access of their systems.
  4. Companies offering Infra/Application Managed Services on AWS can now safely peer into customer Amazon VPC and provide monitoring and management of AWS resources.
Practice 25) Use Amazon VPC: It is highly recommended that migrate all your new workloads inside Amazon VPC rather than Amazon Classic Cloud. I also strongly recommend to migrate your existing workloads from Amazon Classic cloud to Amazon VPC in phases or one shot which ever is feasible. In addition to the benefits of the VPC that is detailed in the start of the article, AWS has started introducing lots of features which are compatible only inside VPC and in the AWS marketplace as well there are lots of products which are compatible only with Amazon VPC.  So make sure you leverage this strength of VPC. If you require any help for this migration please contact me. 


readers feel free to suggest more.. I will link relevant ones in this article

Need Consulting help ?

Name

Email *

Message *

DISCLAIMER
All posts, comments, views expressed in this blog are my own and does not represent the positions or views of my past, present or future employers. The intention of this blog is to share my experience and views. Content is subject to change without any notice. While I would do my best to quote the original author or copyright owners wherever I reference them, if you find any of the content / images violating copyright, please let me know and I will act upon it immediately. Lastly, I encourage you to share the content of this blog in general with other online communities for non-commercial and educational purposes.

Followers